Pre-Winter Sale Special - Limited Time 70% Discount Offer - Ends in 0d 00h 00m 00s - Coupon code: sntaclus

A company has a typical RAG-enabled, customer-facing chatbot on its website.
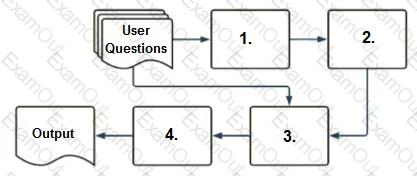
Select the correct sequence of components a user ' s questions will go through before the final output is returned. Use the diagram above for reference.

A.

1.embedding model, 2.vector search, 3.context-augmented prompt, 4.response-generating LLM

B.

1.context-augmented prompt, 2.vector search, 3.embedding model, 4.response-generating LLM

C.

1.response-generating LLM, 2.vector search, 3.context-augmented prompt, 4.embedding model

D.

1.response-generating LLM, 2.context-augmented prompt, 3.vector search, 4.embedding model

A Generative Al Engineer is building a system which will answer questions on latest stock news articles.

Which will NOT help with ensuring the outputs are relevant to financial news?

A.

Implement a comprehensive guardrail framework that includes policies for content filters tailored to the finance sector.

B.

Increase the compute to improve processing speed of questions to allow greater relevancy analysis

C Implement a profanity filter to screen out offensive language

C.

Incorporate manual reviews to correct any problematic outputs prior to sending to the users

A team uses Mosaic AI Vector Search to retrieve documents for their Retrieval-Augmented Generation (RAG) pipeline. The search query returns five relevant documents, and the first three are added to the prompt as context. Performance evaluation with Agent Evaluation shows that some lower-ranked retrieved documents have higher context relevancy scores than higher-ranked documents. Which option should the team consider to optimize this workflow?

A.

Use a reranker to order the documents based on the relevance scores.

B.

Modify the prompt to instruct the LLM to order the documents based on the relevance scores.

C.

Use a different embedding model for computing document embeddings.

D.

Increase the number of documents added to the prompt to improve context relevance.

A Generative AI Engineer has been reviewing issues with their company ' s LLM-based question-answering assistant and has determined that a technique called prompt chaining could help alleviate some performance concerns. However, to suggest this to their team, they have to clearly explain how it works and how it can benefit their question-answering assistant. Which explanation do they communicate to the team?

A.

It allows you to break down complex tasks into multiple independent subtasks. This enables the assistant to generate more comprehensive and accurate responses.

B.

It allows you to reduce the latency of your applications. By having multiple chains participating in the response as a chain, you increase the rate at which the response is generated.

C.

It allows you to decrease the effort involved in crafting a prompt. Chains make it possible to reuse prompt text across multiple different use cases.

D.

It reduces the average cost of a typical request. Chains make more efficient use of the tokens produced to generate higher quality responses with fewer tokens.

A Generative AI Engineer is building a RAG application that will rely on context retrieved from source documents that are currently in PDF format. These PDFs can contain both text and images. They want to develop a solution using the least amount of lines of code.

Which Python package should be used to extract the text from the source documents?

A.

flask

B.

beautifulsoup

C.

unstructured

D.

numpy

Which indicator should be considered to evaluate the safety of the LLM outputs when qualitatively assessing LLM responses for a translation use case?

A.

The ability to generate responses in code

B.

The similarity to the previous language

C.

The latency of the response and the length of text generated

D.

The accuracy and relevance of the responses

A Generative AI Engineer has set up an endpoint with AI Guardrails turned on to block any incoming requests that divulge PII. They also have inference tables enabled for this endpoint. If an end user sends their phone number in their prompt, what will appear in the inference table for that record?

A.

The full answer that would have been sent without the PII block will appear in inference tables.

B.

The record will not appear in inference tables because it contains PII.

C.

The request will appear, but the response column will be blank.

D.

The request will appear, but the response will be the error indicating that the request was blocked due to PII.

A Generative AI Engineer has deployed a RAG application to production. Its Vector Search index is built from a Delta table that receives incremental updates every hour from an upstream ETL pipeline. The team wants the index to automatically reflect source-table changes without manual re-indexing and without changing the endpoint used by downstream applications.

Which approach should the engineer use?

A.

Replace the current index with a Direct Vector Access index and push updates through a custom streaming job.

B.

Update the pipeline mode to continuous mode rather than triggered mode.

C.

Schedule a job to rebuild the index every hour after the ETL pipeline finishes.

D.

Use a Delta Sync index so changes in the source Delta table are automatically synchronized to the index.

A small and cost-conscious startup in the cancer research field wants to build a RAG application using Foundation Model APIs.

Which strategy would allow the startup to build a good-quality RAG application while being cost-conscious and able to cater to customer needs?

A.

Limit the number of relevant documents available for the RAG application to retrieve from

B.

Pick a smaller LLM that is domain-specific

C.

Limit the number of queries a customer can send per day

D.

Use the largest LLM possible because that gives the best performance for any general queries

A Generative Al Engineer is building a RAG application that answers questions about internal documents for the company SnoPen AI.

The source documents may contain a significant amount of irrelevant content, such as advertisements, sports news, or entertainment news, or content about other companies.

Which approach is advisable when building a RAG application to achieve this goal of filtering irrelevant information?
A.

Keep all articles because the RAG application needs to understand non-company content to avoid answering questions about them.

B.

Include in the system prompt that any information it sees will be about SnoPenAI, even if no data filtering is performed.

C.

Include in the system prompt that the application is not supposed to answer any questions unrelated to SnoPen Al.

D.

Consolidate all SnoPen AI related documents into a single chunk in the vector database.