A mining company is building a land classification system by using a dataset of several million images. The dataset contains raw image files in various formats. The images do not contain annotations or metadata that indicates types of land cover.
Which type of dataset has the company collected for modeling?
A company wants to identify groups for its customers based on the customers ' demographics and buying patterns.
Which algorithm should the company use to meet this requirement?
A company wants to build an ML application.
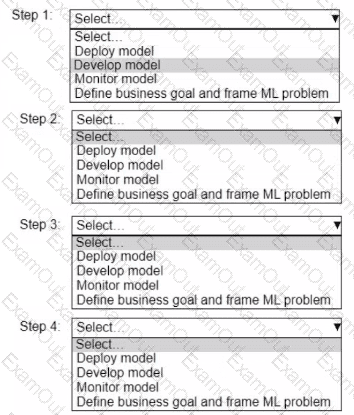
Select and order the correct steps from the following list to develop a well-architected ML workload. Each step should be selected one time. (Select and order FOUR.)
• Deploy model
• Develop model
• Monitor model
• Define business goal and frame ML problem

A retail store wants to predict the demand for a specific product for the next few weeks by using the Amazon SageMaker DeepAR forecasting algorithm.
Which type of data will meet this requirement?
Which AWS service helps select foundation models (FMs) for generative AI use cases?
A company wants to develop an educational game where users answer questions such as the following: " A jar contains six red, four green, and three yellow marbles. What is the probability of choosing a green marble from the jar? "
Which solution meets these requirements with the LEAST operational overhead?
A financial company is developing a generative AI application for loan approval decisions. The company needs the application output to be responsible and fair.
Which solution meets these requirements?
Sated and order the steps from the following bat to correctly describe the ML Lifecycle for a new custom modal Select each step one time. (Select and order FOUR.)
• Define the business objective.
• Deploy the modal.
• Develop and tram the model.
• Process the data.
A company trained an ML model on Amazon SageMaker to predict customer credit risk. The model shows 90% recall on training data and 40% recall on unseen testing data.
Which conclusion can the company draw from these results?
A company has set up a translation tool to help its customer service team handle issues from customers around the world. The company wants to evaluate the performance of the translation tool. The company sets up a parallel data process that compares the responses from the tool to responses from actual humans. Both sets of responses are generated on the same set of documents.
Which strategy should the company use to evaluate the translation tool?