You need to schedule the population of the medallion layers to meet the technical requirements.
What should you do?
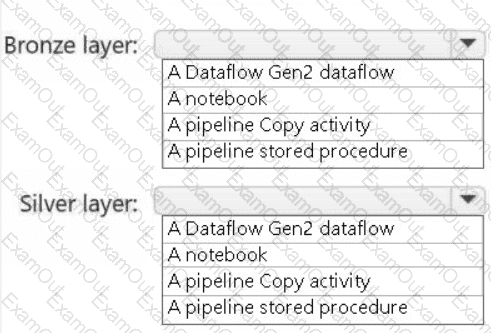
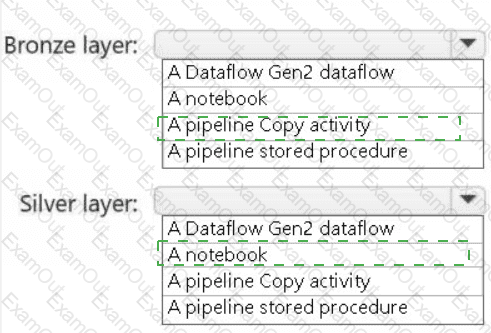
You need to recommend a method to populate the POS1 data to the lakehouse medallion layers.
What should you recommend for each layer? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
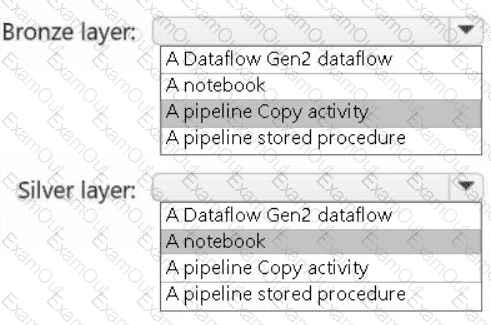 A screenshot of a computer Description automatically generated
You need to populate the MAR1 data in the bronze layer.
Which two types of activities should you include in the pipeline? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
You have a Fabric workspace named Workspace1.
You plan to configure Git integration for Workspace1 by using an Azure DevOps Git repository. An Azure DevOps admin creates the required artifacts to support the integration of Workspace1 Which details do you require to perform the integration?
You need to create the product dimension.
How should you complete the Apache Spark SQL code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
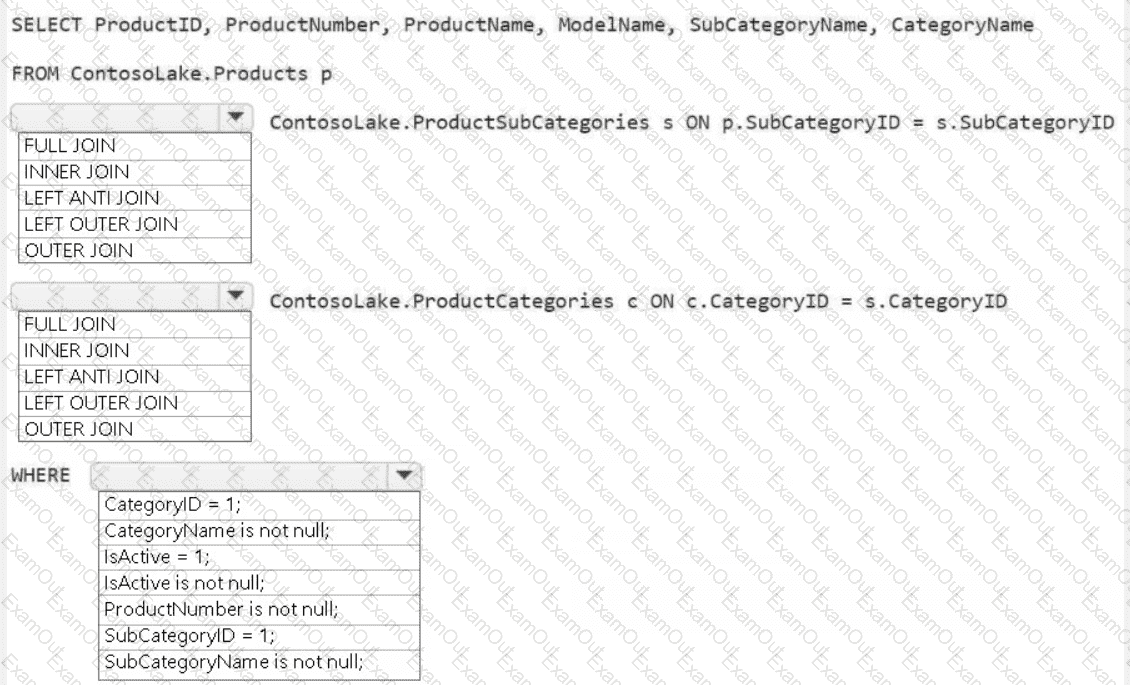
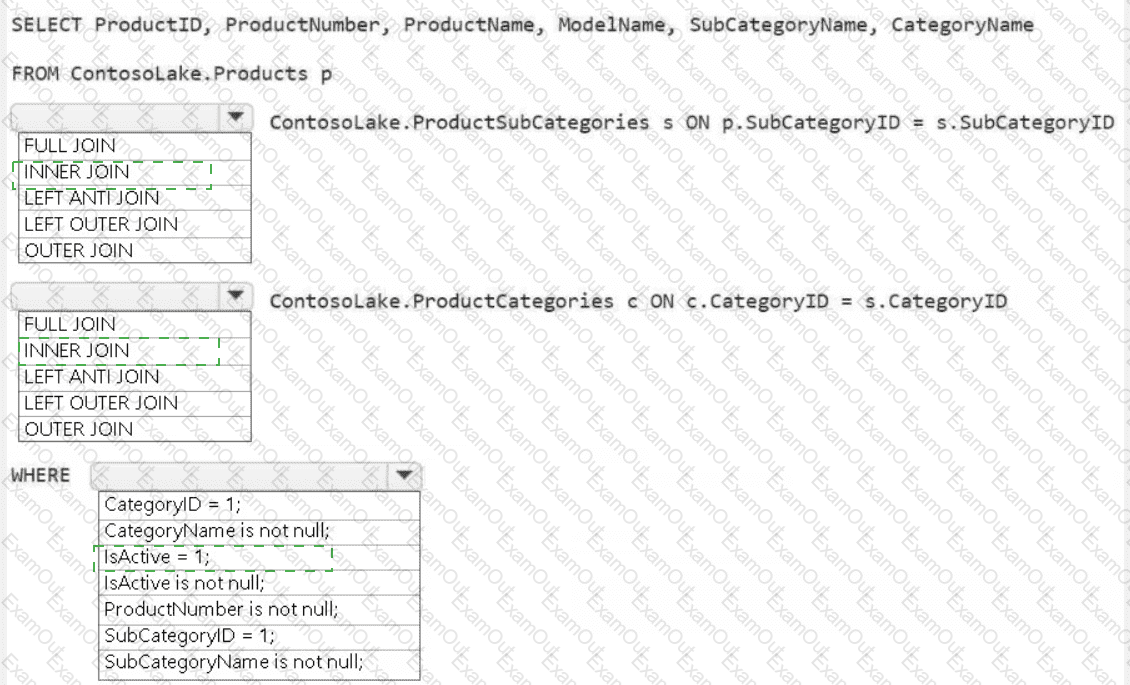
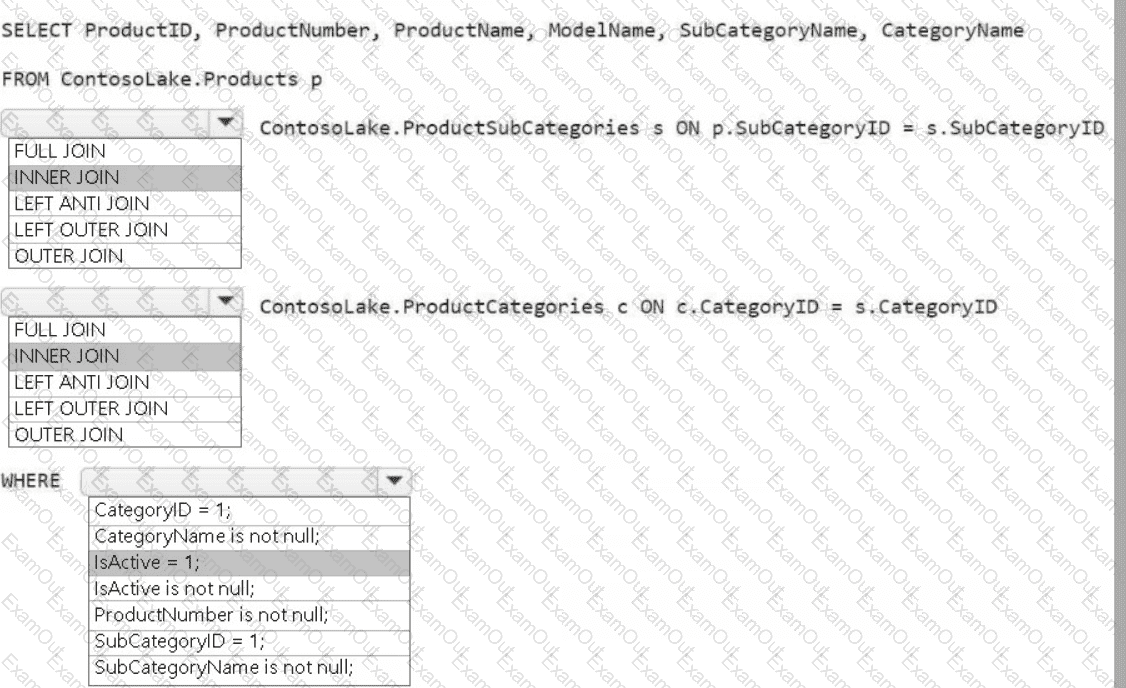 A screenshot of a computer Description automatically generated
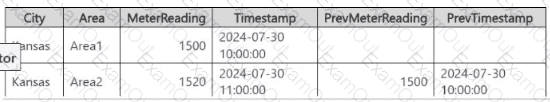
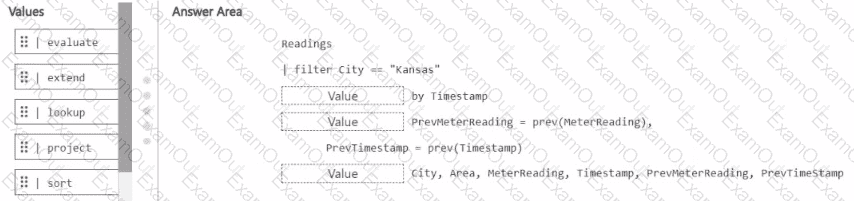
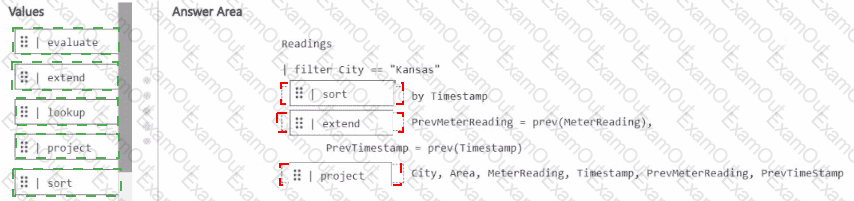
You have a KQL database that contains a table named Readings.
You need to build a KQL query to compare the Meter-Reading value of each row to the previous row base on the ilmestamp value
A sample of the expected output is shown in the following table.
You have a Fabric workspace named Workspace1 that uses Git integration and is connected to the main branch of an Azure Repos Git repository named Repo1.
Multiple developers sync from Workspace1.
A hotfix was introduced two commits ago in main. The most recent commit in main contains unrelated changes that are NOT approved for release.
You need to deploy only the hotfix, while keeping the main branch history intact. The solution must minimize disruptions for other developers working in main.
What should you do?
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
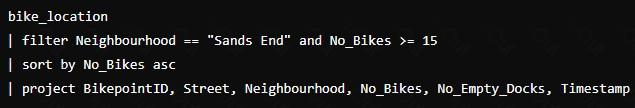
You have a Fabric eventstream that loads data into a table named Bike_Location in a KQL database. The table contains the following columns:
BikepointID
Street
Neighbourhood
No_Bikes
No_Empty_Docks
Timestamp
You need to apply transformation and filter logic to prepare the data for consumption. The solution must return data for a neighbourhood named Sands End when No_Bikes is at least 15. The results must be ordered by No_Bikes in ascending order.
Solution: You use the following code segment:
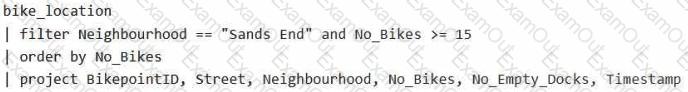
Does this meet the goal?
You have a Fabric workspace that contains a lakehouse named Lakehousel.
You plan to create a data pipeline named Pipeline! to ingest data into Lakehousel. You will use a parameter named paraml to pass an external value into Pipeline1!. The paraml parameter has a data type of int
You need to ensure that the pipeline expression returns param1 as an int value.
How should you specify the parameter value?
You have a Microsoft Power Apps app named App1 that has data stored in Microsoft Dataverse. You need to access the App1 data by using Fabric. What should you use?